-
How much does an integrated inductor in an AI server cost
These inductors are often packaged in sizes like 0410-0740, and each piece can cost between 0. Depending on the machine, some servers might need 50 inductors, with others requiring over 200. 09 billion in 2025 and expected to reach USD 2. The digital age has ushered in unprecedented demand for high-performance AI servers, propelling inductors into. Organizations deploying AI infrastructure often discover that GPU servers account for only 60% of their total investment. Traditional. The Inductor for AI Server Market Size was valued at 2,400 USD Million in 2024. The rapid maturation of artificial intelligence workloads has materially altered.
-

How to make an elbow at the bottom of the cable tray
Whether you are a DIY enthusiast, electrician, or metalworker, this tutorial will help you create cable tray elbows like a pro. 🎯 Topics Covered: Tools for cable tray elbow making Step-by-step fabrication process Professional welding & bending tips Quality control and. This video shows metal fabrication techniques, DIY cable tray projects, and tips for perfect bends and joints. We need to change the shape to suit the shape of trunking. The length of the bottom side (bottom diagonal) after bending the cable tray should be equal to the width of the cable. How to design cable tray? Most projects are roughly defined at the start of cable tray design. For projects that are not 100 percent defined before design start, the cost of and time used in coping with continuous changes during the engineering and drafting design phases will be substantially less. The bends, tees, crosses, risers and reducers of wire mesh cable tray can be easily and quickly made live at the project by using a bolt cutter.
[PDF Version]
-
Indian manufacturer s AI server 40G
Altos Computing, an Acer group company and a global provider of high-performance computing and AI infrastructure solutions, on Monday rolled out its Make-in-India AI server portfolio, and termed it a step toward strengthening India's sovereign AI and data centre ecosystem. PLI scheme marks the beginning of India 's manufacturing venture India's PLI scheme initiates local manufacturing of high-performance computing servers. Mega Networks leads the way by producing Intel's latest server processors in India. The company is committed to supporting India's ambition to become a global hub for AI innovation and digital infrastructure. Local. Its new Make in India AI servers target enterprises, researchers, and data centers moving from pilot projects to real deployment where compute speed and supply now matter. That is the gap Altos Computing is trying to address with its. Lenovo announced at CES 2026 in Las Vegas on January 9, 2026, that it will design and manufacture its next-generation artificial intelligence servers in India, marking a major boost to the country's advanced technology manufacturing ambitions.
[PDF Version]
-
AI Server Backup Power
AI training requires tremendous processing power, raising IT server rack power density from 5-8 kW/cabinet to over 30 kW/cabinet or more, making traditional UPS systems insufficient for high-power demands in AI computing data centers. Our innovative products enable efficient, reliable, and scalable power conversion, ensuring uninterrupted operation of these critical facilities. As. Five years ago, the average data center rack drew 8. Today, a single NVIDIA GB200 NVL72 AI rack draws 132 kW — more than 16 times as much. By 2028, racks are projected to reach 1 MW. It's a fundamental rewrite of how data centers provision, generate, store, and back. The increased introduction of high-performance AI servers around the world has made securing stable power supplies for data centers a major issue. Traditional UPS and backup systems, designed for general-purpose servers, often struggle to accommodate the high-density GPU racks, rapid load fluctuations, and millisecond-level uptime requirements of AI. In today's hyper-competitive world of artificial intelligence (AI) data centers, continuous uptime isn't just desirable, it's mission-critical.
[PDF Version]
-
Why are AI server power supplies so expensive
AI is fueling high demand for compute power, spurring companies to invest billions of dollars in infrastructure. In data. AI server costs are rising at a pace that is breaking procurement plans, budget models, and deployment timelines across the industry. Every layer of the stack, including GPU modules, memory, networking, power, and cooling, has repriced sharply heading into 2026. The market, estimated at $5 billion in 2025, is projected to witness a Compound Annual Growth Rate (CAGR) of 15% from 2025 to 2033, reaching.
-
AI Training and Analysis Server
The AI Training server is a specialized computing system meticulously crafted to streamline the training of AI models. <div><br></div><div>As the process of training AI models demands substantial computational resources due to its inherent complexity, the AI training server is. We tested and analysed next-gen GPU computing configurations for AI workloads — covering training speed, inference latency, distributed performance, and real cost-per-result. Whether you are running your first LLM fine-tuning job or managing a production AI platform at scale, this guide gives you. Configure the ideal setup for training or inference, or get guidance from our experts. “With expert support and remote management options, Liquid Web offers flexible, reliable GPU hosting designed to meet the needs of businesses handling complex, high-performance tasks. Unlike general-purpose servers, they're optimized for tasks such as machine learning (ML), deep learning. Train dense deep neural networks and achieve state-of-the-art results at scale. Execute enterprise-grade AI workloads and productivity with a turnkey Ant PC NVIDIA GPU Server powering your every need.
[PDF Version]
-
What cloud AI servers are available in Uganda
Discover the best Artificial Intelligence companies in Uganda. 19 companies are available in this region. Hire the top Artificial Intelligence company in Uganda for your project!.
-
AI Server Chassis Performance Test
Geekbench AI is a cross-platform AI benchmark that uses real-world machine learning tasks to evaluate AI workload performance. For the current Artificial Analysis System Load Test (AA-SLT), NVIDIA's B200 is the most performant accelerator for LLM inference. It leads on peak throughput and output speed per query, though the right choice can still vary by model, deployment goal and budget. Which accelerator has the highest. This standard provides formal methods for the performance benchmarking for AI server systems, including approaches for test, metrics and measure. Share your thoughts on. Allion's Closed-Chassis Testing evaluates servers in their fully assembled, operational state—faithfully reproducing real customer usage scenarios. Test results show that when servers run for extended periods and heat accumulates inside the chassis, issues emerge that are nearly impossible to. Artificial intelligence (AI) computing differs from generic computing in terms of device formation, operators, and usage. AI server systems, including AI server, cluster, and high-performance computing (HPC) infrastructures are designed specifically for this purpose.
[PDF Version]
-
AI computing server H800
NVIDIA's H800 GPU brings advanced AI performance and scalable architecture to enterprise data centers, delivering high-speed training and inference for large language models while enabling robust security and flexible deployment. Meanwhile, the H800 offers nearly identical performance to the H100 for standalone tasks while navigating export restrictions. If you're deploying large-language model training or inference in mainland China, Hong Kong, or Macao—and your cluster relies on PCIe-based infrastructure—the NVIDIA H800 PCIe 80 GB is likely your most viable high-bandwidth option under current U. It delivers near-H100 compute. In the race to develop advanced AI models, NVIDIA GPUs like the H100 and H800 are the undisputed compute powerhouses. However, their true potential is unleashed only when they are connected by an equally powerful, low-latency, and high-bandwidth network fabric. With optimized performance, efficiency improvements, and innovative features, this. The NVIDIA H800 GPU utilizes Hopper architecture to deliver record-breaking AI and HPC performance for enterprise data centers.
[PDF Version]
-
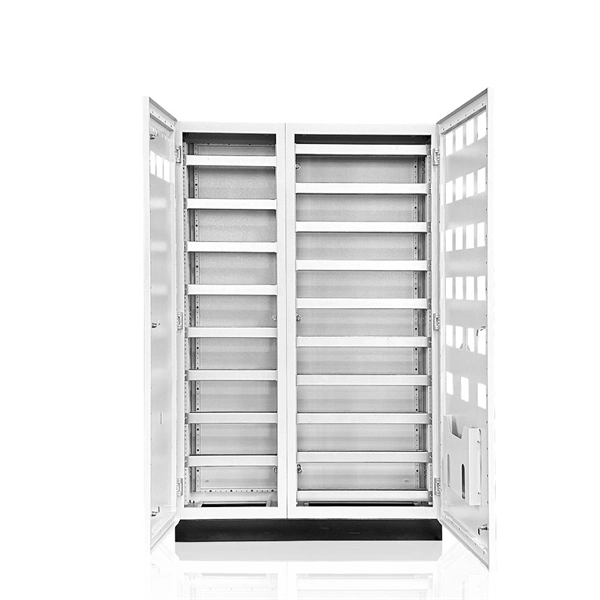
How to connect the grounding wires of a mobile power distribution box
Attach a ground wire from one of the threaded studs (A) at the bottom of the housing, to the mounting plate (B). The ground resistance between all system parts shall be < 0. This position is the connection point of the grounding wire in the. System grounding Ground or earth provides a common return path for electric current in an electric circuit. Grounding is needed for electric safety and it also creates a reference point. Here are the steps on how to ground a power distribution box: 1. Each DISTRIBUTION BOX and controller must be grounded.
-
How many cores are typically used in a fiber optic filament tray
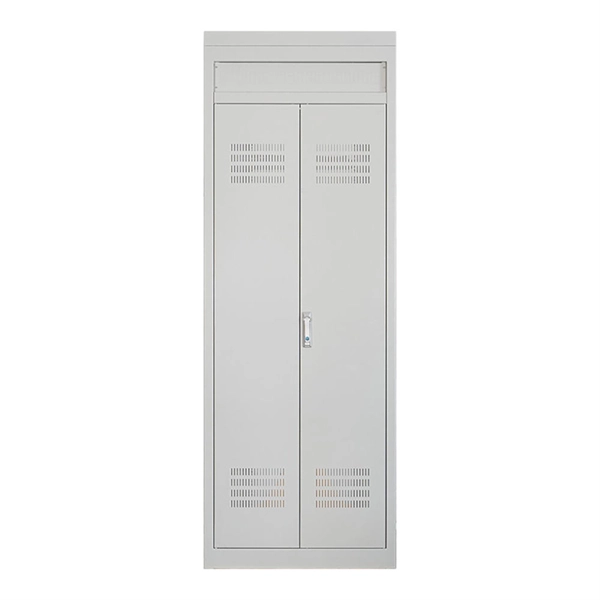
For most setups, cables with 12, 24, or 48 cores are common choices, ensuring compatibility with modern equipment and ease of management. Fiber cores are the heart of fiber optic cables, transmitting light signals that carry data. Made from either high-quality glass or plastic, the core plays a critical role in determining the cable's performance. The total number of cores for a 1pc fiber patch cable is calculated as the number of. Common fiber cores include 1 core, 2 cores, 6 cores, 8 cores, etc. When selecting fiber, the first step is to determine single mode or multimode, and. The number of optical cores in an optical fiber is the total number of equipment interfaces multiplied by 2, plus 10% to 20% of the spare quantity, and if the communication mode of the equipment has serial communication and equipment multiplexing, you can reduce the number of cores. In terminal boxes and closures, core count is directly related to: Common configurations include: These configurations do not represent performance differences, but rather. One key factor is the number of cores, which impacts how much data you can transmit.
[PDF Version]